The Modern Data Stack for Startups in 2026: What You Actually Need
Search for “modern data stack” and you will find diagrams with twenty logos, arrows in every direction and a price tag that assumes you have a data team of ten. For most startups, that is the wrong starting point.
A good data stack for a young company is small, cheap and built to answer the questions that matter now. It should also be ready for AI, because the same clean, connected data that powers your dashboards is what makes AI features work.
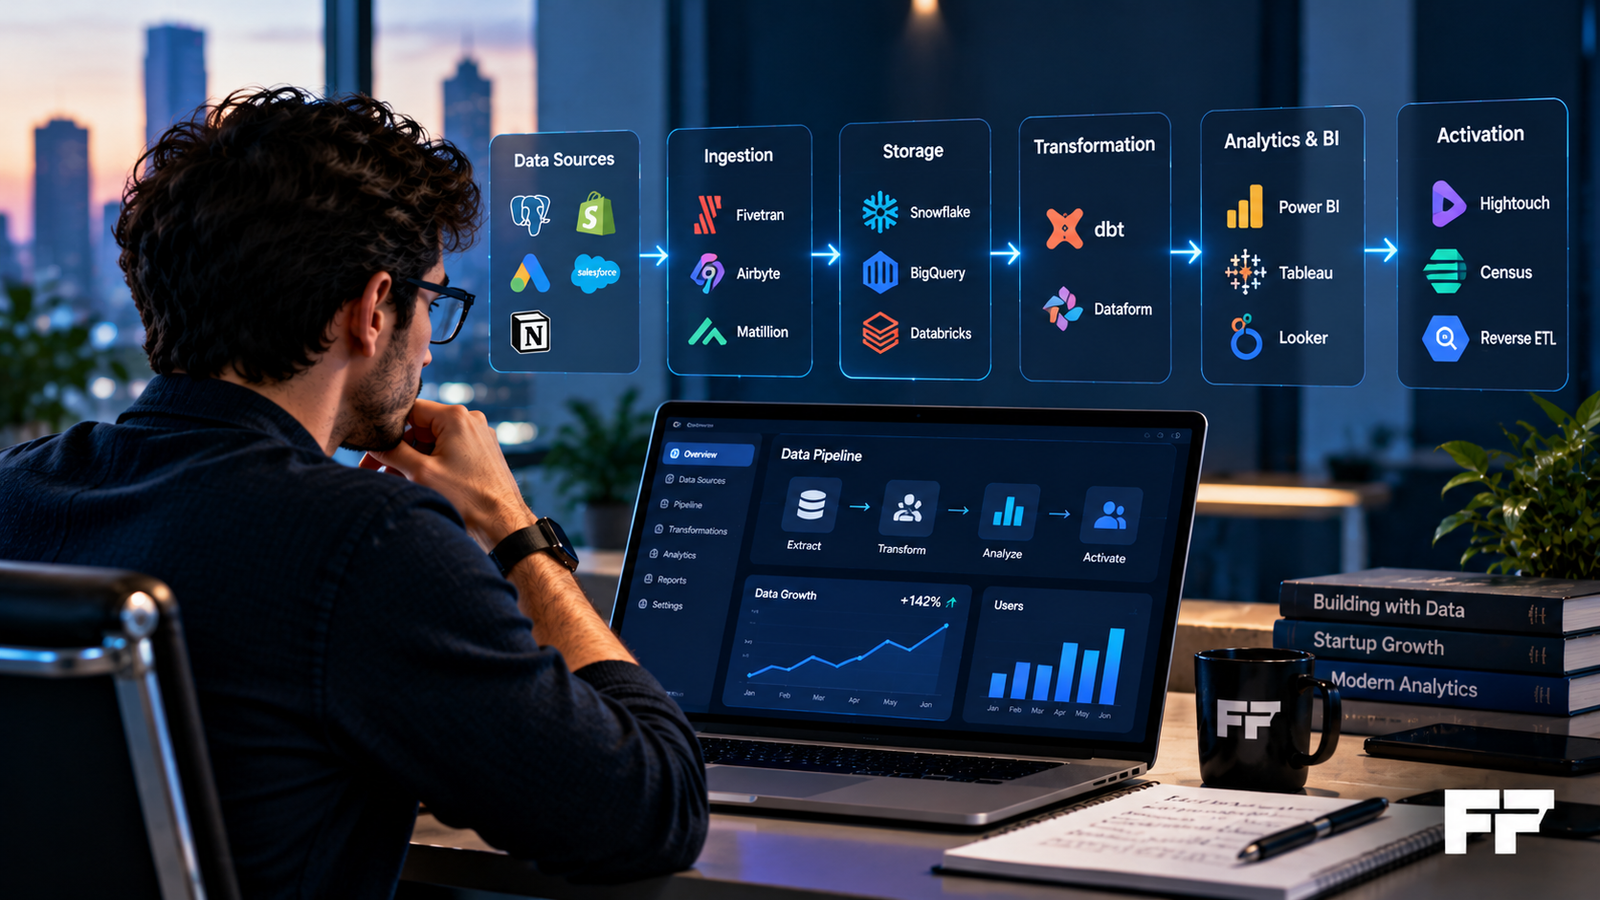
This guide walks through each layer of a lean stack, what it does, which tools are commonly used, and when you actually need it.
What a Data Stack Is For
Strip away the jargon and a data stack does four things:
- Collects data from the tools your company uses.
- Stores it in one place.
- Cleans and models it so the numbers mean the same thing to everyone.
- Delivers it to people, dashboards and AI systems that need it.
Every tool in the stack does one of those jobs. If a tool does not clearly serve one of them, you probably do not need it yet.
Stage 0: Before You Need a Stack
If you are pre revenue or have only a handful of customers, you probably do not need a data stack at all. Your product database, your payment provider’s dashboard and a spreadsheet will answer your questions.
What you should do at this stage is build good habits:
- Track key product events from day one, such as sign ups, activation and core actions.
- Use consistent names for customers, plans and products across tools.
- Write down your definitions. What counts as an active user? When is a customer churned?
These habits cost almost nothing now and save months of cleanup later.
Layer 1: Data Sources
These are the tools that generate your data: your product database, payment processor, CRM, support desk, marketing platforms and product analytics.
The main decision here is product analytics. Tools such as PostHog, Amplitude and Mixpanel capture how users behave inside your product. Pick one early and track events consistently. Switching later is painful because historical data rarely transfers cleanly.
Layer 2: Ingestion
What it does: Copies data from your source tools into your central storage on a schedule.
Common tools: Fivetran and Airbyte are widely used. Fivetran is managed and simple. Airbyte offers an open source option you can host yourself.
When you need it: Once you have three or more tools whose data you want to combine, such as matching payments to product usage to support tickets.
Startup tip: Many of these tools price by data volume. Sync only the tables and fields you actually use.
Layer 3: Storage (the Warehouse)
What it does: Holds all your data in one place where it can be queried together.
Common tools: Google BigQuery, Snowflake and Postgres are common choices. Many startups begin with Postgres or BigQuery because they are inexpensive at small volumes.
When you need it: As soon as you want to answer questions that span multiple tools.
Startup tip: Cloud warehouse bills can surprise you. Set budget alerts from day one and watch for dashboards that run expensive queries every few minutes.
Layer 4: Transformation
What it does: Turns raw data into clean, consistent tables. This is where you define what revenue, active users and churn mean, once, for everyone.
Common tools: dbt is the most common choice. It lets you write transformations in SQL, version them and test them.
When you need it: The moment two people report different numbers for the same metric. That argument is the sign you need a single, shared definition.
Why it matters for AI: AI features rely on clean, well defined data. The same models that power your dashboards can feed your AI assistants.
Layer 5: Business Intelligence
What it does: Turns your clean tables into dashboards and reports people can use.
Common tools: Metabase is popular with startups for its simplicity. Looker, Tableau and Power BI are common in larger companies.
When you need it: Once leadership needs regular visibility into metrics without asking an engineer every time.
Startup tip: Start with a handful of dashboards tied to decisions. A dashboard nobody acts on is decoration.
Layer 6: Activation
What it does: Sends clean data back into your operational tools, such as pushing product usage into your CRM so sales can see which accounts are most engaged.
Common tools: Reverse ETL tools such as Hightouch and Census.
When you need it: When sales, marketing or support teams need warehouse data inside the tools they already use.
Layer 7: The AI Layer
This is the newest layer, and the one most Solo founders now ask about.
What it does: Makes your data available to AI models, usually by indexing documents and records so an AI system can search them and use them in answers.
Common approaches: Vector search built into existing databases, dedicated vector databases, or retrieval features offered by AI platforms.
When you need it: When you are building AI features that must use your company’s own data, such as a support assistant or an internal knowledge tool.
Key point: The AI layer depends on everything below it. If your data is messy upstream, the AI will surface that mess to users.
A Lean Stack by Company Stage
| Stage | What you need | What you can skip |
|---|---|---|
| Pre revenue | Product analytics, clear definitions | Everything else |
| Early revenue | Warehouse, ingestion for key tools, simple BI | Reverse ETL, complex orchestration |
| Growing team | Transformation with dbt, shared metric definitions | Multiple BI tools |
| Scaling | Activation, data quality monitoring, AI layer | Custom built tools you can buy |
Costly Mistakes to Avoid
- Buying the enterprise stack too early. Tools priced for large companies drain a startup budget fast.
- Skipping definitions. Without agreed metric definitions, more tools just produce more conflicting numbers.
- No owner. Someone must be responsible for the stack, even part time.
- Syncing everything. Moving every table from every tool raises costs and creates clutter.
- Ignoring privacy. Centralizing data also centralizes risk. Control who can see customer information.
The FounderFeat Take
The best data stack for a startup is the smallest one that answers your real questions reliably. Add layers only when a clear problem demands them.
Build it well and you get two benefits for the price of one: better decisions today, and the clean foundation your AI features will need tomorrow.
Sources
https://nkktech.com/blog/best-modern-data-stack-startups-2026