How to Evaluate an LLM Before You Build on It: A Founder’s Framework
Every few weeks a new model tops a leaderboard. The announcement comes with charts showing it beating competitors on reasoning, coding and math. Founders read the headlines, switch providers, and then discover the new model is worse at the one thing their product actually needs.
Public benchmarks are useful for tracking the field. They are a poor way to choose the model your business depends on. The only evaluation that matters is how a model performs on your tasks, with your data, at your volume and your budget.
This framework shows how to build that evaluation without a research team.
Why Public Benchmarks Mislead
Benchmarks measure what their designers chose to measure. That rarely matches what your product needs.
They test general ability. A benchmark might test graduate level science questions. Your product might need to extract invoice numbers from messy PDFs.
They can be gamed. When a benchmark becomes famous, model builders optimize for it. Scores rise faster than real world usefulness.
They ignore cost and speed. A model that scores two points higher but costs five times as much and responds three times slower may be the wrong choice.
They ignore your format. Your product may need consistent JSON output, a specific tone or strict length limits. Benchmarks do not test those.
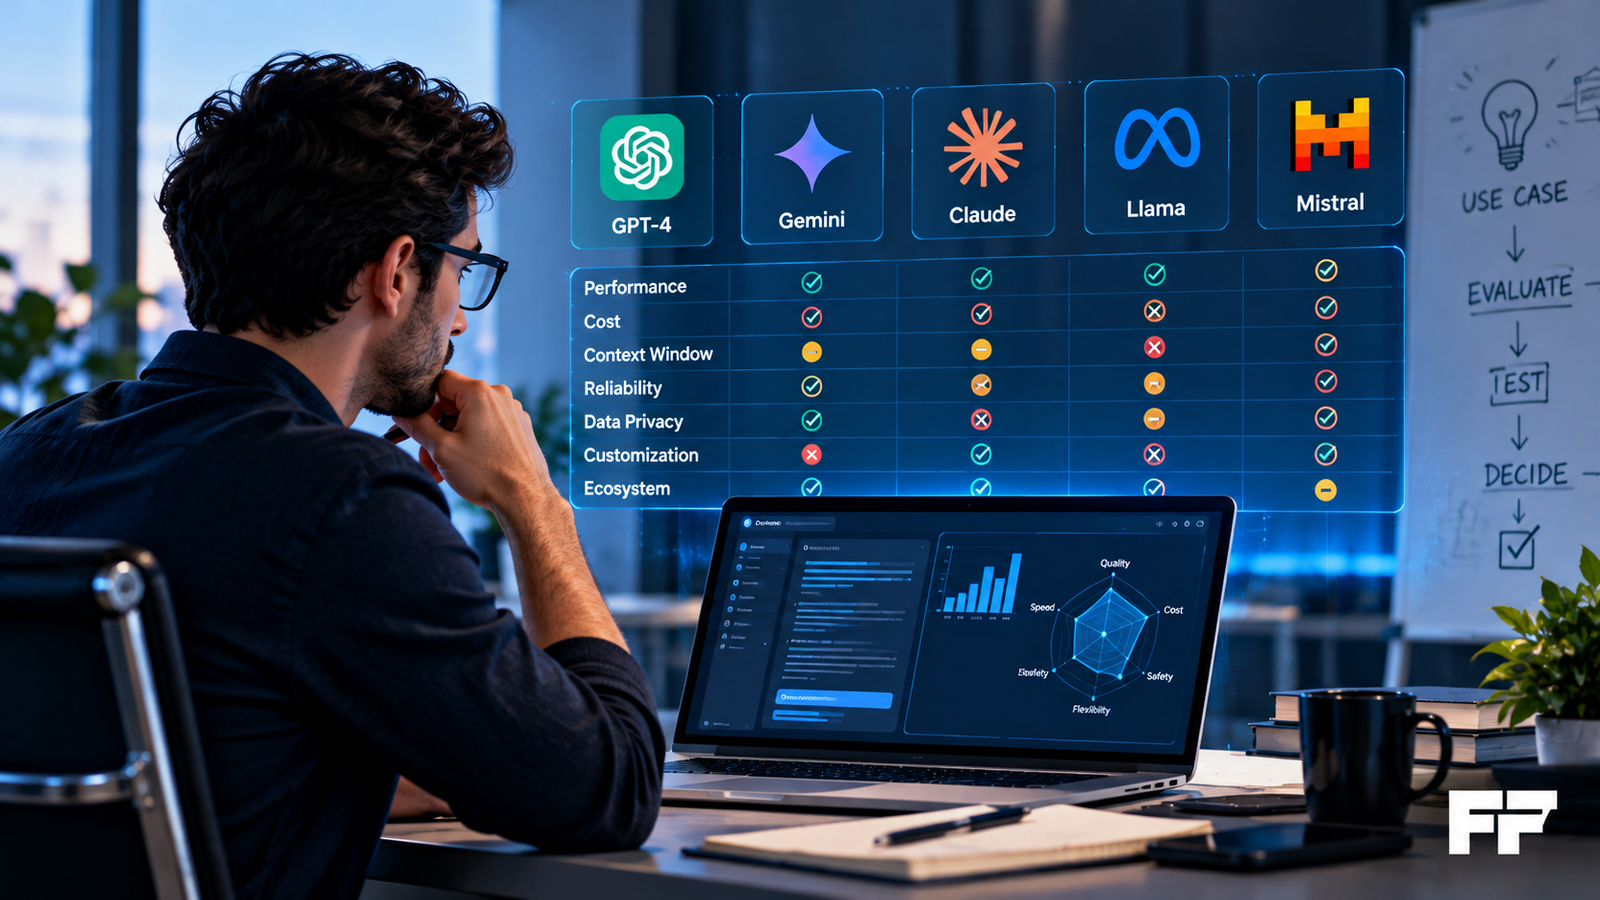
That is why most serious teams now run their own evaluations. It is also why many companies end up using several models at once. Research from F5 found organizations running or evaluating an average of seven models, choosing different ones for different jobs.
Step 1: Define the Job Precisely
Start by writing down exactly what the model must do. Vague goals produce vague evaluations.
Weak: “Answer customer questions.”
Strong: “Answer questions about order status, returns and shipping using our policy documents. Respond in under 120 words, in a friendly tone, and escalate anything involving refunds above $200.”
The strong version tells you what to test, what counts as success and what counts as failure.
Step 2: Build a Test Set From Real Examples
Your test set is the most valuable asset in the whole process. It is a collection of real inputs with known good outputs.
Aim for 50 to 200 examples to start. Pull them from real work: past support tickets, real documents, actual customer requests. Include a mix of cases:
- Common cases: the everyday requests that make up most of your volume.
- Hard cases: ambiguous questions, messy inputs and unusual formats.
- Edge cases: the rare situations where a mistake would be costly or embarrassing.
- Trap cases: requests the model should refuse or escalate.
For each example, write down what a good answer looks like. That can be an exact expected output or a short list of things the answer must include and avoid.
Keep this test set private and versioned. You will reuse it every time you consider a new model.
Step 3: Choose What to Measure
Pick a small number of metrics that map directly to business outcomes.
| Metric | What it tells you | How to measure |
|---|---|---|
| Accuracy | Is the answer correct? | Compare against your expected outputs |
| Format compliance | Does it follow your structure? | Automated checks on length, fields or JSON validity |
| Safety and refusals | Does it avoid bad actions? | Score the trap cases separately |
| Latency | How fast does it respond? | Time each request |
| Cost per task | What does each answer cost? | Tokens used multiplied by price |
| Consistency | Does it give stable answers? | Run the same input several times |
You do not need all six for every product. A customer facing assistant cares a lot about safety and tone. An internal data extraction tool cares most about accuracy and cost.
Step 4: Score the Outputs
There are three practical ways to score results, and most teams combine them.
Automated checks
Anything with a clear right answer can be checked by code. Did the output include the correct order number? Is the JSON valid? Is it under the word limit? These checks are fast and cheap.
Model graded scoring
For open ended answers, you can use a strong model to grade outputs against a rubric you write. This scales well but needs calibration. Check a sample of its grades by hand to confirm it agrees with human judgment.
Human review
For the highest stakes cases, have a person on your team review outputs. Keep the rubric simple, such as a 1 to 5 score for correctness and a yes or no for whether the answer could go to a customer.
Step 5: Compare Models Fairly
Run every candidate model on the same test set with the same prompt structure. A few rules keep the comparison honest:
- Tune prompts reasonably for each model. Models respond differently to instructions. A fair test gives each one a sensible prompt, not one written for a competitor.
- Use the settings you will use in production. If you will run at a certain temperature or with certain tools, test that way.
- Record everything. Save inputs, outputs, scores, costs and timings so you can revisit decisions later.
Then look at the results together. The best choice is usually the cheapest model that clears your accuracy and safety bar, not the model with the highest score.
Step 6: Keep Evaluating After Launch
Evaluation is not a one time event. Models change, providers update versions and your users will find inputs you never imagined.
- Add real failures to your test set. Every time a user reports a bad answer, turn it into a test case.
- Rerun tests before any model change. Before switching versions or providers, confirm nothing important got worse.
- Monitor live quality. Sample production outputs each week and score them against the same rubric.
Over time, your test set becomes a competitive advantage. It captures what good looks like for your specific product, something no public benchmark can do.
A Lightweight Version for Very Small Teams
If you are a solo founder or a team of three, you can still do this in an afternoon:
- Collect 30 real examples in a spreadsheet.
- Write the ideal answer, or the key points, for each one.
- Run them through two or three models.
- Score each output from 1 to 5 and note the cost.
- Pick the cheapest model that scores well on the cases that matter most.
That simple process will beat choosing a model from a leaderboard nearly every time.
Mistakes to Avoid
- Testing on demo inputs. Clean, simple examples make every model look good. Real inputs are messy.
- Chasing every new release. Switching models too often wastes engineering time. Switch only when your own tests show a clear gain.
- Forgetting cost at scale. A small price difference per request becomes a large number at a million requests a month.
- Skipping the trap cases. The most damaging failures usually come from requests the model should have refused.
The FounderFeat Take
Leaderboards tell you which model is best in general. Your business needs to know which model is best for you. The founders who build their own simple test sets make faster, cheaper and safer decisions, and they stop being swayed by every launch announcement.
Start with 30 real examples this week. It is one of the highest value hours you can spend before building on AI.